
Industrial process system integration reduces production bottlenecks when the constraint is no longer a single machine problem. It becomes valuable when material flow, machine settings, production schedules, quality decisions, and maintenance actions are disconnected enough that one delay creates several more downstream.
A faster press, converting machine, drying section, or packaging cell will not automatically raise output if operators are still waiting for approvals, recipes are entered manually, work-in-progress is invisible, or quality data arrives after the affected batch has moved on. Integration addresses those handoffs. It connects equipment, controls, workflow rules, and operational data so that the production line can respond as one system rather than a collection of isolated assets.
The practical test is simple: if a team can identify where production stopped but cannot reliably explain why it stopped, or what condition upstream created the loss, an integration gap may be contributing to the bottleneck.
When integration is the right response to a bottleneck
Not every capacity problem calls for a systems project. A worn mechanical component, inadequate staffing, unstable raw materials, or an unrealistic production plan must be addressed directly. Industrial process system integration is most effective when the constraint comes from poor coordination between otherwise capable resources.
Common signals include frequent changeover delays, repeated waiting between process stages, conflicting production priorities, manual transcription of machine or quality information, and excess work-in-progress accumulating before one operation. Another signal is a line that performs well on an individual-equipment basis but misses overall throughput, delivery, or yield targets.
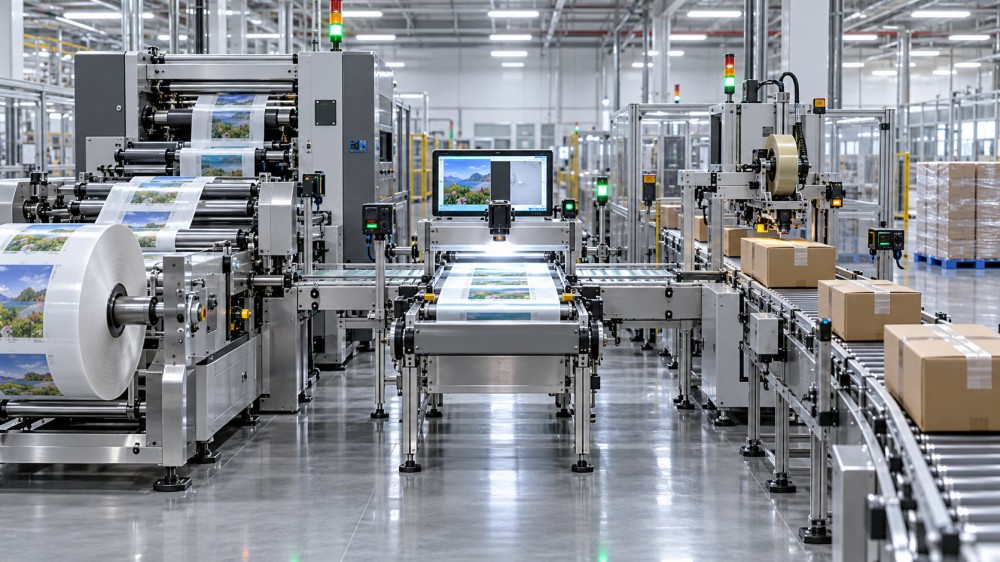
Consider a packaging operation where printing, inspection, slitting, and packing each appear to have sufficient nominal capacity. If the inspection station repeatedly holds material because job specifications, approved samples, and live production settings are stored in separate places, the issue is not merely inspection speed. Linking job data, machine recipes, inspection results, and release status can remove avoidable waiting and rework.
In papermaking, an upstream adjustment may affect moisture, basis weight, or reel quality later in the process. In textile finishing, recipe changes, batch traceability, and scheduling decisions can influence whether a downstream stage receives material in the right sequence. In digital printing, color-management data must remain aligned with the job and substrate rather than being treated as a separate quality task. These are coordination problems, and they are often more valuable to solve than a narrow automation upgrade.
Start with the constraint, not the technology stack
A common mistake is to begin with a preferred platform, a new dashboard, or the promise of a fully connected factory. That approach can produce attractive screens while leaving the production constraint untouched. The first decision should be which loss mechanism is limiting output.
Map the process from order release to finished-goods handoff. Include material availability, setup, machine processing, inspection, hold points, rework loops, maintenance interruptions, and information approvals. The map should show both physical flow and information flow. Material may move quickly while decisions move slowly, or a machine may be available while the required job recipe is not.
Then distinguish between a true bottleneck and a symptom. A downstream machine that is frequently idle may not be the constraint; it may simply be starved by poor sequencing upstream. A department with the longest queue may be absorbing variability created earlier in the line. Integration should be designed around the source of instability, not around the most visible queue.
The integration layers that affect throughput
Useful integration is rarely one connection between two applications. It normally involves several layers, each serving a different operational purpose.
Equipment and control connectivity
This layer collects relevant machine states, alarms, counts, process values, and downtime reasons from equipment or local control systems. Its value is not simply data volume. It provides a shared view of whether a machine is running, waiting, blocked, in setup, or producing material that requires attention.
Older equipment does not always need to be replaced to participate. In some cases, a limited set of reliable signals is enough to improve dispatching, downtime analysis, or material tracking. The important question is whether the signal is accurate enough to support a decision. Capturing every available tag can raise cost and complexity without improving throughput.
Workflow and production execution
Production execution connects work orders, routing, operator actions, quality checks, and actual process events. This is where an operation can enforce the difference between “the job has started” and “the job is ready to start.” A job may need approved artwork, verified material, a released recipe, and available tooling before it should be dispatched.
For high-mix manufacturing, this layer often produces more value than a broad automation program because it controls variation. When jobs differ in materials, dimensions, print files, tolerances, or packaging requirements, the system must make the right instruction available at the point of work. Otherwise, changeovers become dependent on memory, local spreadsheets, and informal communication.
Quality and traceability integration
Quality data is often treated as a compliance record maintained after production. That leaves a major improvement opportunity unused. When inspection, test, or visual-quality outcomes are linked directly to the production run, the system can identify patterns before the same defect consumes more capacity.
The goal is not to automate every quality judgment. It is to ensure that a failed check, an out-of-range process condition, or a customer-specific requirement reaches the person who can act before more material is produced. Traceability is especially important where rework decisions, material substitution, or product release can otherwise create delays across several stages.
Planning, inventory, and maintenance data
A line cannot meet its schedule when the schedule assumes materials, labor, tools, or machines are available when they are not. Integration between planning, inventory, maintenance, and the shop floor improves the credibility of the production plan. It can reveal whether an urgent job is genuinely executable or merely prioritized on paper.
This does not mean every planning change should be pushed instantly to every machine. Constant rescheduling can destabilize the line. Effective systems establish rules for when a schedule change is released, who can authorize it, and how active work is protected from unnecessary interruption.
Choose the smallest integration scope that changes the decision
The strongest projects usually start with a bounded production problem: reduce avoidable waiting before a critical operation, shorten recipe verification during changeovers, improve response to recurring downtime, or prevent quality holds from becoming invisible queues. A focused scope creates a clearer baseline and exposes whether the new workflow is being used correctly.
Starting with one value stream does not mean designing a dead end. Interfaces, naming conventions, master data ownership, and cybersecurity responsibilities should support later expansion. But the first deployment should prove a complete operational loop: capture an event, interpret it consistently, assign responsibility, take action, and confirm the outcome.
A broad “single source of truth” initiative often fails when ownership is unclear. The maintenance system may own asset history, the planning system may own demand and work orders, and a production execution layer may own actual shop-floor status. Integration should synchronize the information needed by each function without creating competing records for the same decision.
Data discipline determines whether the system helps or distracts
Inconsistent product codes, ungoverned recipe versions, vague downtime labels, and informal unit conversions can undermine even well-designed architecture. If one system records a job as complete when a machine finishes its run while another records completion only after quality release, reported throughput will be disputed rather than improved.
Before connecting systems, define the operating meanings of key events: released, started, paused, completed, held, scrapped, reworked, and available. Define who may change a recipe, who closes a quality hold, and how exceptions are recorded. These decisions may appear administrative, but they determine whether the line receives usable instructions.
Downtime classification deserves particular care. A long list of reasons encourages inaccurate selections; a list that is too broad hides actionable patterns. Use categories that match the decisions the operation can make, such as material shortage, setup issue, equipment fault, quality hold, or schedule change. Refine them only when the data reveals a need.
Design for the people making decisions during the shift
Integration creates value when it reduces uncertainty at the point of action. Operators need clear current instructions and a quick way to record exceptions. Supervisors need to see whether the constraint is running, starved, blocked, or producing unacceptable output. Maintenance personnel need enough context to prioritize work without searching through disconnected records. Quality teams need visibility into which material and settings are affected by a finding.
Overloading each role with the same dashboard is counterproductive. A line-side screen should highlight the next decision, while operational reviews can use broader trend views. Alerts also need restraint. If every machine event creates a notification, important exceptions disappear into noise. Alerts should correspond to conditions that require an assigned response.
Training should cover the changed work, not only the software interface. A new tablet, barcode scan, or production screen may change who confirms a job, when a hold is raised, or how a changeover is released. Adoption problems often reflect unresolved workflow questions rather than resistance to technology.
When integration will not remove the bottleneck
System integration cannot compensate for an operation with insufficient physical capacity, chronic material defects, an unsuitable product design, or unstable process parameters. It may make those conditions more visible and easier to manage, but visibility is not capacity.
It is also a poor first move when the underlying process has not been agreed. Automating a disputed routing, inconsistent quality rule, or frequently changing approval path simply distributes confusion faster. Stabilize the core operating method, then connect it.
There are cases where a local improvement is more appropriate. A single recurring mechanical failure may require engineering work. A fixed constraint with predictable demand may justify additional capacity. An integration project should be selected because coordination is the source of loss, not because connectivity is assumed to be the modern answer.
A practical way to sequence the project
- Define the bottleneck in operational terms. State where flow is lost, what event triggers the loss, and which downstream consequence matters.
- Establish a baseline. Use current records and direct observation to understand waiting, rework, downtime, changeovers, and quality holds around the constrained area.
- Map the data and decision handoffs. Identify where information is created, altered, delayed, or re-entered.
- Set the minimum viable operational loop. Specify the few signals, workflows, and ownership rules needed to improve one decision.
- Test against real exceptions. Include material substitutions, rejected inspections, machine stoppages, priority changes, and incomplete jobs.
- Measure the flow outcome. Review whether waiting, unstable sequencing, avoidable rework, or time to respond has improved, rather than judging success by the number of connected systems.
Sector-specific context matters throughout this work. A printing line may depend on accurate color and artwork control; a food-contact packaging process may require tightly managed quality release; a textile operation may need reliable batch and recipe continuity. Intelligence resources such as GSI-Matrix can help teams compare how process, equipment, and market requirements interact across specialized manufacturing segments. That context is useful when a technically sound integration design must also fit the realities of a particular production model.
The decision to integrate should therefore follow the bottleneck, the flow of information, and the accountability for action. When those three are connected, the production system can expose constraints earlier and coordinate a response before local delays become lost output.
Related News
- Commercial Insights on Global Emerging Markets in PrintMay 14, 2026Global emerging markets insights for print businesses: discover high-potential segments, entry strategies, and risk signals to improve timing, reduce uncertainty, and win faster in growth markets.
- Greening Manufacturing: Which Projects Pay Back Faster?May 14, 2026Greening manufacturing projects that pay back fastest often cut energy, waste, and downtime in 6–24 months. See which upgrades finance teams should approve first.
- Choosing food safety compliance training programs for audit readinessOct 20, 2026Compare food safety compliance training programs for audit readiness. Learn how to verify practical skills, assess providers, and secure traceable records before you invest.
- How to select industrial components for heavy-duty shock loadsOct 18, 2026Select industrial components for heavy duty use with confidence. Learn how to assess shock loads, compare ratings, and verify assemblies to reduce damage and costly downtime.